

Read an upside-down, blurry page scan with Indra OCR on a CPU
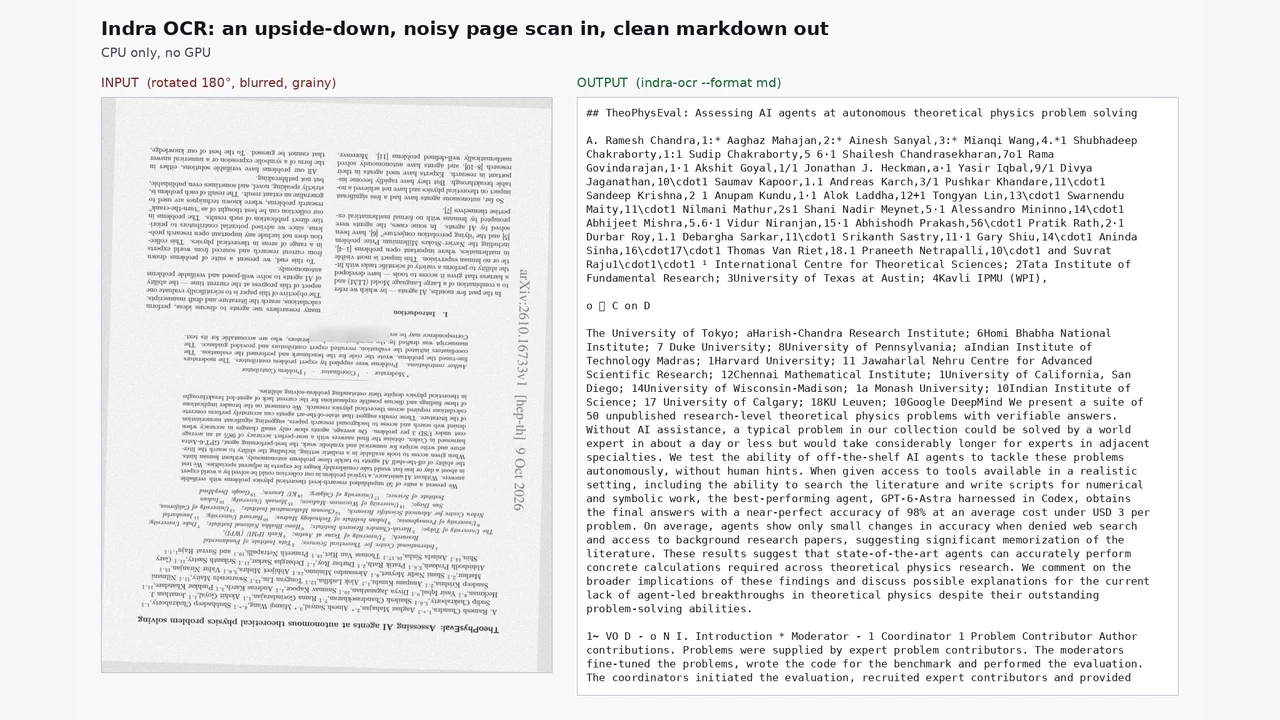
We tested Indra OCR (first published Oct 10–13) on an 8-vCPU Intel Xeon, CPU only. We gave it a page rotated upside down, blurry and grainy: page 1 of the TheoPhysEval paper. It turned the page upright and the title came out exact. On our heavily blurred copy (indra-ocr 0.3.2), about 83% of the abstract's words were right (151 of 182) and the body had a few errors. On a less blurry copy, the abstract came out with every word right. Superscripts came out garbled and the sideways arXiv stamp was dropped.
Try it yourself
What you get
Markdown text from a scanned page, even one that is upside down, blurry and grainy, with no GPU. Expect some wrong words on a badly damaged scan.
Tools
- Indra OCR 0.3.2 (Datalab)
- Any recent CPU; we used an 8-vCPU Intel Xeon
Steps
- Install it with pip install indra-ocr==0.3.2 (we used 0.3.2). It downloads its model files from Hugging Face the first time, then checks for updates at most once a day.
- Run indra-ocr input.png --format md > output.md on your scan or PDF.
- For a PDF that already has a text layer, the default mode uses it; --mode ocr forces every page through OCR. We did not test this, because our input was an image.
- Check the whole text by hand, especially superscripts, footnote marks and sideways text. On our heavily blurred page, superscripts came out garbled, the sideways arXiv stamp was dropped and some words in the abstract were wrong.
Watch out: Code Apache-2.0. Weights: modified OpenRAIL-M, free for personal use, research, and organizations at or under $20M in revenue or funding; not for anyone offering a product that competes with Datalab's. No region limits.
Proof / source
Tested by AgentPlays Our own runs on Oct 16, 2026, with indra-ocr 0.3.2 on an 8-vCPU Intel Xeon, CPU only, on a rebuilt copy of the damaged page: same output all three times, title exact, about 83% of the abstract's words right. On a less blurry copy, the abstract came out with every word right. Model card on Hugging Fa
Read the original source ↗ Discussion ↗
Related
Convert HTML to Markdown on a CPU with Microsoft MarkItDown
We tested Microsoft MarkItDown 0.1.8 on Oct 16: it converted Project Gutenberg ebook #4 (Lincoln's Gettysburg Address, HTML) to Markdown on an 8-vCPU Intel Xeon, CPU only…
Discussion
Remove an image background on a CPU with rembg
We tested rembg on Oct 16 with a self-made test image: a red circle with a yellow square on a green background.
Let your AI agent do the bookkeeping legwork in Dougs while you approve every change
Tom Eberle open-sourced dougs-cli (MIT), an unofficial command-line tool for the French accounting platform Dougs, so an agent can work in their company's books.
Get a second opinion on a $1,800 car repair quote from the shop's own inspection video
After a routine service, a shop recommended about $1,800 of work on Kyle Blanchard's Mazda and sent an inspection video.